llms.txt vs robots.txt vs sitemap.xml: what is the difference?
July 28, 2026
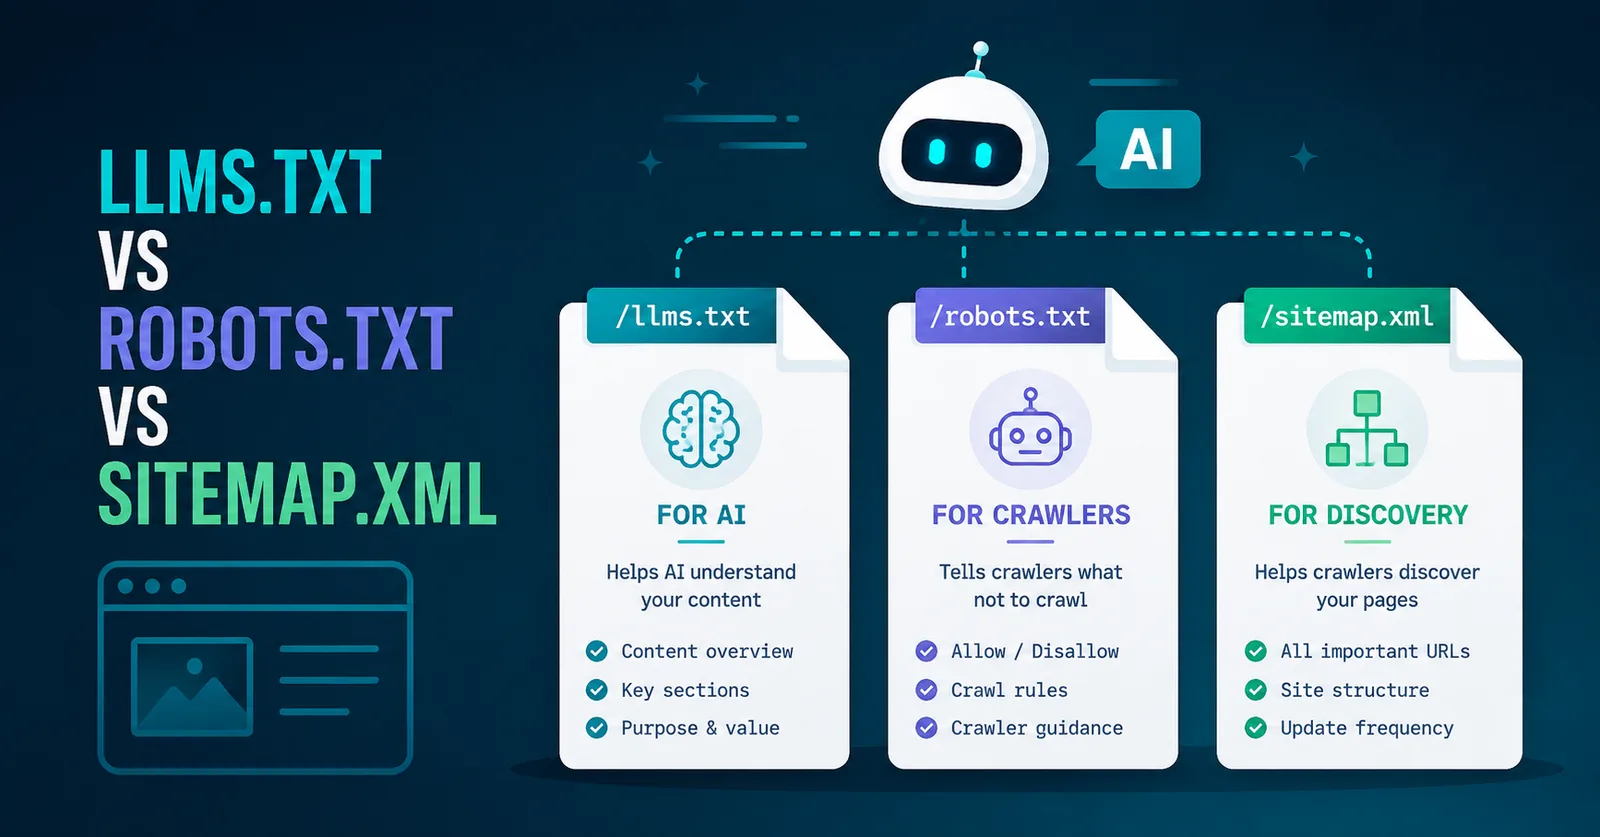
If you already maintain a robots.txt and an XML sitemap, llms.txt can feel like one more file to babysit for unclear reasons. It is a fair reaction. The names look similar, they all live at the root of your domain, and plenty of articles blur them together.
They are not competing formats. Each one talks to a different audience about a different thing, and none of them replaces another. Here is the clean version.
The short answer
robots.txt controls crawler access. sitemap.xml lists your URLs for search indexing. llms.txt presents your content in readable Markdown for AI tools. They serve different audiences and do not conflict, so a site can publish all three.
| robots.txt | sitemap.xml | llms.txt | |
|---|---|---|---|
| Format | Plain text directives | XML | Markdown |
| Purpose | Permission: what crawlers may fetch | Discovery: which URLs exist | Presentation: what your content says |
| Audience | Search and AI crawlers | Search engines | AI assistants, agents, and tooling |
| Contains | Allow and Disallow rules | URLs, last-modified dates, priorities | Titles, links, descriptions, and (in llms-full.txt) full page text |
| Read by Google Search | Yes | Yes | No |
| Standard status | Long-established convention | Formal protocol (sitemaps.org) | Community convention, proposed 2024 |
| Typical size | A few lines | Every indexable URL | Curated: your important pages |
The one-line mental model: robots.txt says what a bot may do, sitemap.xml says where things are, and llms.txt says what things mean.
What robots.txt does
robots.txt is the oldest of the three and the simplest in intent. It sits at yourdomain.com/robots.txt and lists rules telling automated crawlers which parts of your site they should not fetch.
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php

Sitemap: https://example.com/sitemap.xml
Two things are worth being precise about, because both are commonly misunderstood.
First, it is advisory, not enforcement. Well-behaved crawlers respect it. Anything else can ignore it entirely. If you need content to be genuinely inaccessible, robots.txt is not the tool. Use authentication.
Second, Disallow blocks crawling, not indexing. A URL you disallow can still appear in search results if other sites link to it, because Google knows the URL exists without having fetched it. To keep a page out of the index, let it be crawled and serve a noindex directive instead.
Increasingly, robots.txt is also where site owners set rules for AI crawlers specifically, with agents like GPTBot, ClaudeBot, PerplexityBot, and Google-Extended given their own blocks. That is still the same job it always did: access control, now with a wider cast of bots.
What sitemap.xml does
An XML sitemap is a machine-readable list of the URLs on your site that you want search engines to know about, usually with a last-modified date and sometimes a change frequency or priority hint.
<url>
  <loc>https://example.com/guides/pour-over/</loc>
  <lastmod>2026-07-01</lastmod>
</url>
Its purpose is discovery, and only discovery. A sitemap helps a search engine find pages it might otherwise miss, particularly on large sites, sites with weak internal linking, or new sites with few inbound links. It does not describe your content, it does not rank you, and being in a sitemap is not a promise of being indexed. Google treats it as a hint.
WordPress has generated a basic sitemap at /wp-sitemap.xml since version 5.5, and SEO plugins like Yoast, Rank Math, and SEO Press replace it with a richer one. If you run any of those, you already have this covered and do not need to think about it.
What llms.txt does
llms.txt is the newest of the three, proposed in 2024 and documented at llmstxt.org. It is a Markdown file at yourdomain.com/llms.txt that gives AI tools a curated, readable version of your site.
# Acme Coffee Roasters

> Small-batch coffee roaster in Portland.

## Products

- [Single-origin beans](https://acme.example/beans): Rotating selection,
  roasted weekly.
- [Subscriptions](https://acme.example/subscribe): Monthly bean deliveries.
The difference from the other two files is the one that matters. robots.txt and sitemap.xml are both about your URLs. Neither one carries a word of your actual content. A crawler that reads both still has to fetch each page and dig your meaning out of rendered HTML, past the navigation, the cookie banner, the related-posts widget, and the layout markup.
llms.txt skips that step. The index file carries titles, links, and short descriptions. Its companion, llms-full.txt, carries the full text of your pages converted to clean Markdown, so a tool can get your actual content in a single fetch instead of crawling and parsing dozens of pages.
That is the honest distinction: those two files describe where your content is, this one describes what your content says.
For a full walkthrough of the format and who reads it today, see What is llms.txt?.
Do they conflict?
No, and it is worth understanding why not, because the question comes up constantly.
They cannot conflict because they do not overlap in function. robots.txt grants or withholds permission. sitemap.xml supplies a URL inventory. llms.txt supplies content. Nothing in one contradicts anything in another. Publishing an llms.txt does not change how Google crawls you, does not affect your sitemap, and does not alter your robots.txt rules.
The one place they touch is a friendly one. robots.txt is a common place to advertise other machine-readable files, which is exactly why the Sitemap: line lives there. The same idea works for your AI files:
# AI Assistants
User-agent: *
Allow: /llms.txt
Allow: /llms-full.txt
That block is a signpost, not a requirement. Nothing breaks without it, and no crawler is obligated to act on it, but it costs nothing and it makes your intent explicit to anything reading your root files.
A related question: does llms.txt conflict with your SEO settings? It should not. If a page is set to noindex in Yoast, Rank Math, or SEO Press, a well-built generator will leave that page out of your AI files too, so your exclusions stay consistent across surfaces rather than leaking through a side door. That behavior is worth checking in whatever tool you use.
Does llms.txt replace robots.txt or my sitemap?
No, on both counts, and anyone suggesting otherwise has the relationship backwards.
Your sitemap feeds Google, Bing, and other search engines. Google has stated plainly that its Search systems, including AI Overviews and AI Mode, do not use llms.txt at all. Dropping your sitemap in favor of an llms.txt would trade a file that demonstrably works for search for a file that has no effect on it.
Your robots.txt is the only place you set crawler permissions. llms.txt has no access-control semantics whatsoever. It cannot block anything, and publishing one does not grant anyone permission they did not already have.
Think of it as additive. You keep the two files that serve search engines, and you add a third that serves a different set of readers.
Which ones does your WordPress site need?
robots.txt: yes, and you probably already have one. WordPress serves a virtual robots.txt automatically, and SEO plugins extend it. The only reason to think about it is if you want to set specific rules for AI crawlers, or if a physical robots.txt file exists in your web root, in which case WordPress stops generating the virtual one and that physical file is what gets served.
sitemap.xml: yes, and you almost certainly already have one. WordPress core generates one, and your SEO plugin likely replaces it with something better. Nothing to do.
llms.txt: worth publishing, with clear eyes about why. It will not help your Google rankings. What it does is give AI tools an accurate, controlled version of your content instead of leaving them to guess from your HTML, and it puts you ahead of a convention that ecommerce platforms have already started shipping by default. For an honest look at how much it is actually being read today, see the real state of llms.txt adoption.
The practical difference between the three is maintenance. Your sitemap updates itself. Your robots.txt rarely changes. An llms.txt written by hand goes stale the moment you publish a post or change a price, and a stale file describing your site wrongly is worse than no file at all. That is the part worth automating.
The short version
Three files, three jobs, no overlap. robots.txt sets crawler permissions. sitemap.xml lists your URLs for search engines. llms.txt hands AI tools your content in a readable form. Keep the first two exactly as they are, add the third if you want a clean machine-readable version of your site, and do not let anyone tell you one replaces another.
Project LLMs.txt is a WordPress plugin that generates your llms.txt and llms-full.txt automatically, adds the robots.txt pointer for you, and respects your existing SEO noindex settings. It is free to install.