llms.txt for WooCommerce: turning products into AI-ready files
August 6, 2026
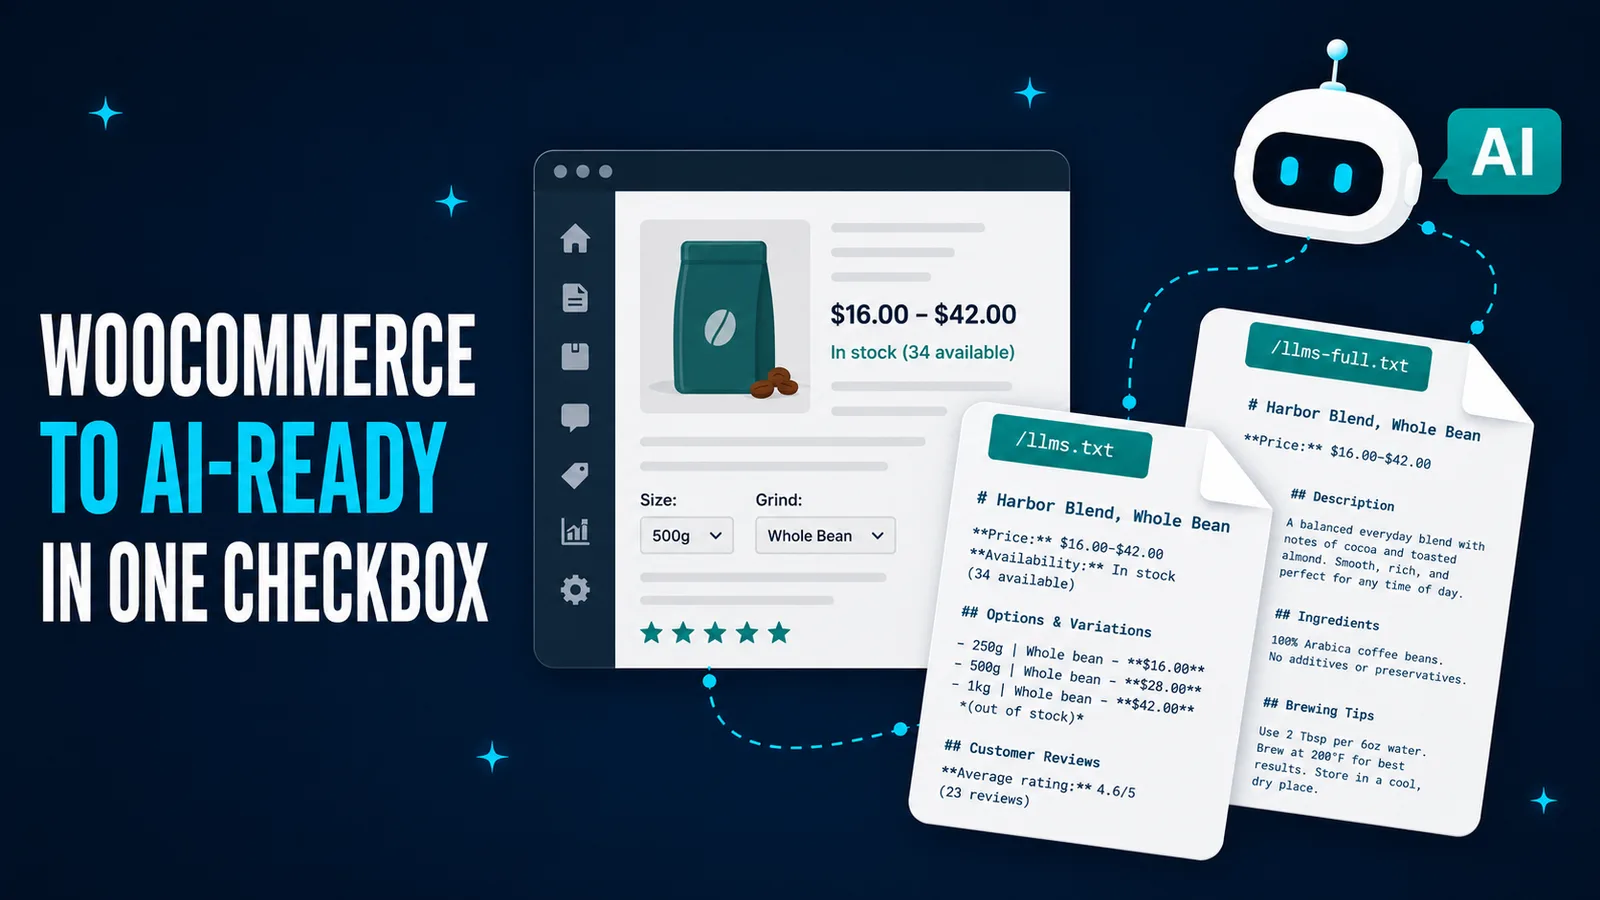
When a user asks an AI assistant about a product on your store, it has to read your product page the same way it reads everything else: by fetching the HTML and trying to work out what all that code means.
There are several problems with this. The price might be split across three nested spans with a currency symbol in its own element. The variation selector is a dropdown populated by JavaScript, so the per-option prices may not exist in the markup at all until something clicks it. Reviews are paginated. Stock status is a CSS class. Somewhere in there is the actual product description, wrapped in tab markup, next to a related-products carousel that looks structurally identical to it.
An assistant can often get the product name right and the price roughly right. Past that it starts guessing.
An llms.txt file solves this by stating all the product information in a format that is easy for AI to understand.
Here is how to produce one using Project LLMs.txt, a free WordPress plugin that builds these files from the catalog you already have.
Turning products on
Install Project LLMs.txt from WordPress.org and activate it. WooCommerce products are supported in the free version, with no separate add-on.
Something to note: products are off by default. A fresh install exports Posts and Pages only, so if you generate without changing anything, your catalog will not be in the file. Open Settings → Content Types, tick Products, then go to the Generate tab and click Generate Now.
Then verify, and see the result for yourself. Open yoursite.com/llms.txt, find the ## Products heading, and check that a product you know well is listed with the right price. If the section is missing entirely, Products did not get enabled. If products are listed but a description looks thin, skip ahead to tuning below.
If you have not set up the plugin at all yet, the general walkthrough is here.
What a product looks like in the output
Every published product gets rendered from a product-specific Markdown template. Not a generic page dump with a price bolted on, but a structure built around what a product is. The output looks like this:
# Harbor Blend, Whole Bean

**URL:** https://example.com/product/harbor-blend/
**SKU:** HB-1000
**Price:** $16.00-$42.00
**Availability:** In stock (34 available)
**Categories:** [Coffee](https://example.com/product-category/coffee/), [Whole Bean](https://example.com/product-category/whole-bean/)
**Tags:** medium roast, blend, house favorite

## Description

A balanced everyday blend with notes of cocoa and toasted almond.

[full product description continues here in Markdown]
Several things there are doing more work than they look like they are.
Price handles the awkward cases. A simple product shows its price. A product on sale shows the original struck through followed by the sale price, so the assistant can tell the difference between a discount and a price change. A variable product has no price of its own in WooCommerce, so instead of exporting an empty field it shows the range across its variations, and that same range appears wherever the product is listed elsewhere in the file. The index and the detail entry always agree.
Stock status is a sentence, not buried in HTML. “In stock (34 available)” when you are managing stock levels, “In stock” when you are not, and “Out of stock” when you are out of stock. No inference required.
Categories link back. Each category is a real Markdown link to its archive, so an assistant reading about one product has a path to the rest of that category.
Variations, priced individually
This is the part that raw HTML handles worst. If your product comes in three sizes at three prices, an assistant reading the page usually sees one number and has no reliable way to attach the others to their options.
In the export it becomes a list:
## Options & Variations

**Size:** 250g, 500g, 1kg
**Grind:** Whole bean, Filter, Espresso

- Size: 250g | Grind: Whole bean - **$16.00**
- Size: 250g | Grind: Filter - **$16.00**
- Size: 500g | Grind: Whole bean - **$28.00**
- Size: 1kg | Grind: Whole bean - **$42.00** _(out of stock)_
The attribute summary comes first, so a reader gets the shape of the options immediately. Then specific combinations with their own prices, and an out-of-stock marker where it applies. Up to ten variations are listed in full, with a count of any remaining, which keeps a product with sixty combinations from swallowing the file.
Reviews and social proof
If a product has approved reviews, they come through as their own section:
## Customer Reviews

**Average rating:** 4.6/5 (23 reviews)

> 5/5 **Dana R.** (July 12, 2026)
> Third bag. The cocoa note is real and it holds up in a moka pot.
The average and the count sit at the top, then the five most recent reviews, each trimmed so a long review does not dominate.
One small deliberate choice: ratings are written as “4.6/5” rather than drawn with star characters. Star glyphs turn into garbage when a web server hands out a .txt file without declaring a character set, and a number parses more reliably anyway.
Related, upsell, and cross-sell products
Your merchandising relationships are already in WooCommerce, and they carry real meaning that gets lost when they are rendered as an anonymous carousel.
Upsells become a You Might Also Like section. Cross-sells become Frequently Bought Together. If you have set neither, WooCommerce’s own related-products logic fills in a Related Products section instead. Each entry is a linked product name with its price, capped at five, and only visible products are listed.
The labels matter more than they might seem. An assistant answering “what should I get with this?” is reading a section that says these are bought together, rather than five product cards in a row that could mean anything.
Tuning it for your store
Two settings are worth a look before you call it done.
Extraction method, if your descriptions look incomplete. Under Settings → Content Extraction there are three modes. Auto is the default and reads your published product content, including blocks and shortcodes. It falls back to loading the full page only when it finds nothing at all.
That fallback is the catch. If your theme or a page builder renders part of the product description outside the editor, Auto gets something, decides it succeeded, and stops. You end up with a description that is present but missing half its content, which is harder to notice than an empty one. If a product in your file reads shorter than the product page does, switch to Full-page scrape, which loads the page the way a browser would and keeps the main content. It is slower, because it requests every page one at a time, and it reads the HTML your server sends, so anything a script draws in after the page loads stays out of reach.
Worth knowing: this only affects the description body. Price, SKU, stock, variations, categories, and reviews are read from WooCommerce directly rather than parsed out of your HTML, which is why they stay correct no matter which extraction mode you pick or how your theme renders the page. The variation pricing that a scraper would never find in a JavaScript dropdown is simply asked for.
Catalog size, if you have more than 200 products. The index lists up to 200 items per content type by default. That covers most sites, but on a 500-product store the remaining 300 are not exported. Check Max Items per Content Type in Settings and raise it to cover your catalog, or decide deliberately that the top 200 is what you want in the file.
The rest are quick calls:
Reviews and related products are toggles. Both on by default. Turn them off for a leaner file, or if your review content is not something you want redistributed.
Images are a toggle too. On by default, which includes the featured image as a Markdown image reference.
Utility pages are excluded automatically. When WooCommerce is active, Cart, Checkout, and My Account are left out without you asking since they are checkout mechanics and not content.
Individual products can be excluded. Use the exclusion picker in Settings to exclude specific products you do not want AI to read. To do it programmatically, for example excluding an entire category or everything below a price, the llmstxt_exclude_ids filter takes the final list of excluded IDs and lets you add to it.
The freshness problem, which is bigger for stores
For a blog, a stale export is a mild annoyance. A post is missing, or a page says something you rewrote last month.
For a store it is worse, because the numbers are the content. Prices change. Sales start and end. Stock runs out. Products get discontinued. Each one of those makes your export wrong in a specific, checkable way, and a machine-readable file confidently stating a price you no longer charge is worse than not publishing one at all.
Two things keep the files current. Automatic regeneration rebuilds them whenever content is published or saved, which is a Pro feature. Public regeneration hooks let any script or importer trigger a rebuild. They are free, and they are how a nightly feed sync or a bulk price update keeps the files in step.
If your catalog changes a few times a year, clicking Generate yourself works fine. If it changes often, set it up to run on its own so it is one less thing to remember.
Is it worth doing?
Nobody can promise you that an AI assistant will recommend your product because you published a Markdown file. The state of llms.txt adoption is early, and we have written at length about not overselling it.
What you can say for sure is smaller than that, and it still matters. When an AI tool does read your store, whether it went looking for the file or simply landed on your domain, it gets your prices, your variations, and your stock status stated plainly instead of inferred from HTML. Being described accurately is not a growth strategy. It is just the floor, and most stores are currently below it.
Project LLMs.txt generates llms.txt and llms-full.txt from your WordPress content. WooCommerce support, including everything described above, is in the free version on WordPress.org.